


The key metrics for measuring generative search success are Brand Visibility, Citation Rate and Sentiment. Together, they show whether your brand appears in AI answers, whether your website is used as a cited source, and how your brand is described. Add Share of Voice for competitive context, then track identifiable AI referral traffic and business outcomes separately.
For marketers and marketing leaders, the goal is a measurement system that helps you choose what to improve and explain progress. An increase in mentions is useful evidence of visibility, but it is not proof of additional revenue.
What are the three core generative search metrics?
Brand Visibility: does your brand appear?
Brand Visibility = valid answers mentioning your brand ÷ all valid answers in the tracked sample × 100.
Count your brand once per answer, even if it appears several times. Define brand names, product names and aliases before collecting the baseline. A mention can be a recommendation, a passing reference or a warning, so visibility alone does not tell you whether the answer helps your brand.
Keep branded questions separate from unbranded discovery questions. “What is Acme?” tests a different job from “Which tools help marketing teams measure AI visibility?” Combining them can conceal weak discovery visibility. See our guide to tracking brand mentions in AI search results for the collection workflow.
Citation Rate: is your website used as a source?
For this guide, owned-domain Citation Rate = valid answers citing at least one URL on your domain ÷ all valid answers in the tracked sample × 100.
Count an answer once even if it cites multiple pages on your domain. Track page-level citations separately when you want to understand which content is performing.
A brand can be mentioned without its website being cited. It can also be cited as a source without receiving a product recommendation. Separate citations to your own website from third-party sources that mention your brand.
Metric names vary between tools. For example, Ahrefs distinguishes domain citations, page citations and mentions. Record the definition behind a dashboard label before comparing numbers from different systems.
Sentiment: how is your brand described?
Classify answers that mention your brand as positive, neutral or negative using a consistent rubric. Positive Sentiment Share = positive mentioning answers ÷ all mentioning answers × 100. Answers that do not mention your brand belong outside this denominator.
Review mixed or ambiguous answers manually. Check accuracy separately: an enthusiastic recommendation with the wrong pricing, capabilities or availability is still a problem. Keep examples of incorrect statements so the team knows which first-party information needs attention. If no answers mention your brand, sentiment share is undefined rather than 0%.
How the metrics work together
Imagine you track 100 AI answers. Your brand appears in 40, your website is cited in 12, and 30 of the 40 brand mentions are positive. Across your brand and two competitors, there are 200 total brand mentions. That means 40% Brand Visibility, 12% Citation Rate, 75% Positive Sentiment Share and 20% Share of Voice. This is a hypothetical example, not a performance benchmark.
The metrics answer different questions, so use them together rather than treating them as one combined score.
Which supporting metrics explain performance?
Share of Voice: how visible are you relative to competitors?
Mention-based AI Share of Voice = your answer-level brand mentions ÷ total answer-level mentions for your brand plus the selected competitors × 100. Count each selected brand once per answer. Multiple brands can appear in one answer.
Include your own brand in the denominator and keep the competitor set fixed. A Share of Voice decline can happen while your visibility stays stable if competitors gain mentions. If you change the set or use citation-based or impression-weighted Share of Voice, label the change rather than presenting it as the same trend. When there are no selected-brand mentions, the share is undefined.
Positioning and cited sources
Visibility tells you whether your brand appears. Positioning explains how it appears: is it recommended, compared with competitors, or associated with a particular strength or weakness?
Citation data helps show which pages on your website and which third-party sources support an AI answer. Look for patterns that reveal content gaps, pages that need improvement, and questions where competitors are better supported. Use our guide to finding sources and domains cited in AI search to investigate specific gaps.
Query fan-outs are background searches AI engines can generate to find supporting information for an answer. Think of them as ‘AI search keywords.’ Where available, they can reveal related questions and searches around the original prompt, helping identify content gaps and optimization opportunities. They are supporting diagnostics, not one of the three core KPIs, and not every internal search is visible.
How to build a comparable measurement baseline
Build your prompt set around the buyer journey. Include non-branded discovery, category, problem and comparison questions, plus branded evaluation and decision questions. Non-branded prompts are especially important because they show whether your brand appears before someone already knows to ask for it. Branded prompts show how your brand, products and reputation are represented when someone is considering you. Group the two types separately by topic and stage of the journey.
Choose AI platforms and surfaces based on your audience. ChatGPT, Perplexity, Gemini, Microsoft Copilot, Claude, Google AI Overviews and Google AI Mode may warrant separate views. Do not assume every brand needs every platform. Keep track of the markets and languages you measure so comparisons remain useful.
Keep prompt sets, competitor sets, markets and brand aliases reasonably consistent over time. When a metric changes, inspect the underlying answers and cited sources to understand what changed and what your team can improve.
Repeat observations before making a decision. The April 2026 preprint Don't Measure Once: Measuring Visibility in AI Search studied repeated outputs across four engines and four Swiss-German sectors. Its scope supports a practical caution about one-off checks, not a universal volatility benchmark for every market.
Note changes to your prompt set, competitor set, markets or tracked platforms when reporting trends. Establish your own baseline and targets by topic, platform and market instead of importing a generic “good visibility” percentage. For implementation sequencing, see the 90-day GEO plan.
Maintain search accessibility and useful content alongside this measurement work. Google's guidance for AI search features says no additional special markup is required. Eligibility does not guarantee inclusion in an AI answer.
What can native tools and website analytics tell you?
Use native reporting and website analytics alongside answer-level monitoring. Their units and coverage differ, so keep the views separate rather than adding them into one visibility total.
Google's Generative AI performance report documentation describes reporting for AI Overviews and AI Mode. It may not appear for properties with insufficient impressions. Treat its link impressions as a different measure from brand mentions in a tracked answer sample.
Bing's AI visibility documentation defines Citation Share around a site's citations relative to all citations for the same grounding query. That is a different denominator from the mention-based Share of Voice above.
In GA4, inspect identifiable AI referrers and their landing pages, engagement and key events. Traffic acquisition uses session-scoped dimensions; it is not a record of every earlier influence on a conversion. Referrer loss, copied URLs and journeys through other channels can leave AI influence unobserved. Ordinary website analytics also cannot tell you the depth of a user's conversation inside an AI assistant.
Our AI referral traffic guide provides a starting point for investigating identifiable visits. Use the current native documentation above for platform reporting scope.
How to turn metric changes into useful actions
Assign an owner and record what changed, which questions it should help, and when you will review the same sample again. A change in citations after an update is an observation, not proof that the edit caused it. Avoid promising a guaranteed visibility lift from schema, formatting or freshness alone.
How should marketers report progress?
A practical starting operating model is daily collection, weekly interpretation and monthly leadership reporting. This is a recommendation, not a universal platform requirement. Adjust frequency to question volume, market volatility, campaign activity and your team's ability to act.
In weekly reviews, inspect meaningful changes by topic and AI engine, check whether the tracked scope has changed, and choose a small number of actions. In the monthly leadership report, show the three core KPIs against the baseline, competitive context, important accuracy issues, completed actions and observable website or business outcomes. Include sample sizes and measurement changes.
Keep traditional SEO and website measures such as impressions, clicks, engagement and conversions where they answer useful questions. Generative search metrics add a view of AI answers; they do not make those business measures obsolete.
Connect identifiable AI referral sessions to key events and CRM outcomes where your setup supports it. Add customer-reported discovery information where available, with its limitations. Do not assign all direct traffic to AI, or describe correlation between visibility and revenue as incremental ROI. For financial reporting, use the AI search optimization ROI framework alongside explicit attribution assumptions.
How Superlines supports the measurement workflow
Superlines helps in-house marketing teams, agencies and enterprise teams monitor AI search visibility across brands and markets. Use Brand Visibility, Citation Rate and Sentiment as the core metrics, then inspect answers, cited sources and competitive context to decide what needs attention.
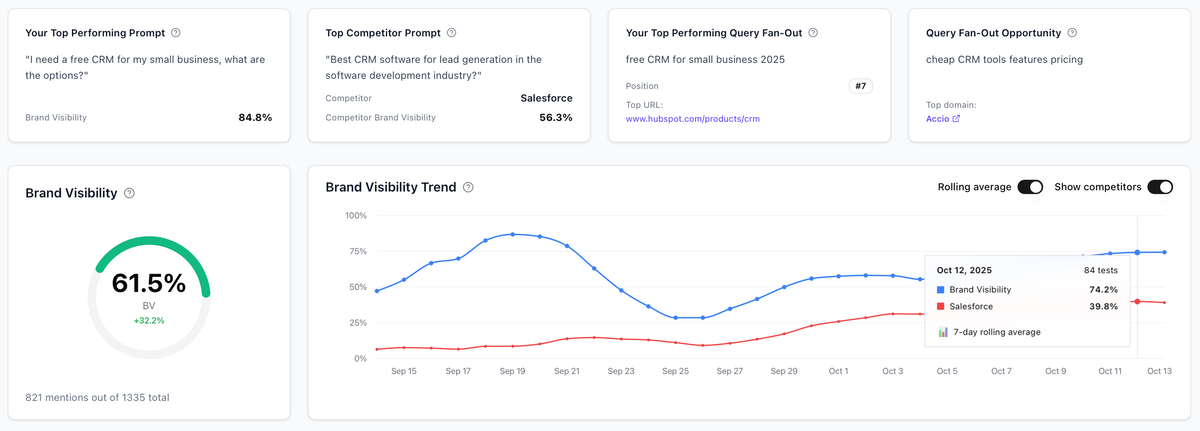
Use the interface to review findings and the Action Center to prioritize recommendations for human review. Exports, API and MCP access can bring the evidence into a reporting or research workflow. Those access methods support the analysis; they do not turn a recommendation into a guaranteed result.
Start a Superlines trial to establish your baseline, or book a demo to discuss your brands, markets and reporting needs.